Bagging vs Boosting vs Stacking: Which Ensemble Method Wins in 2025?
Introduction In machine learning, no single model is perfect.

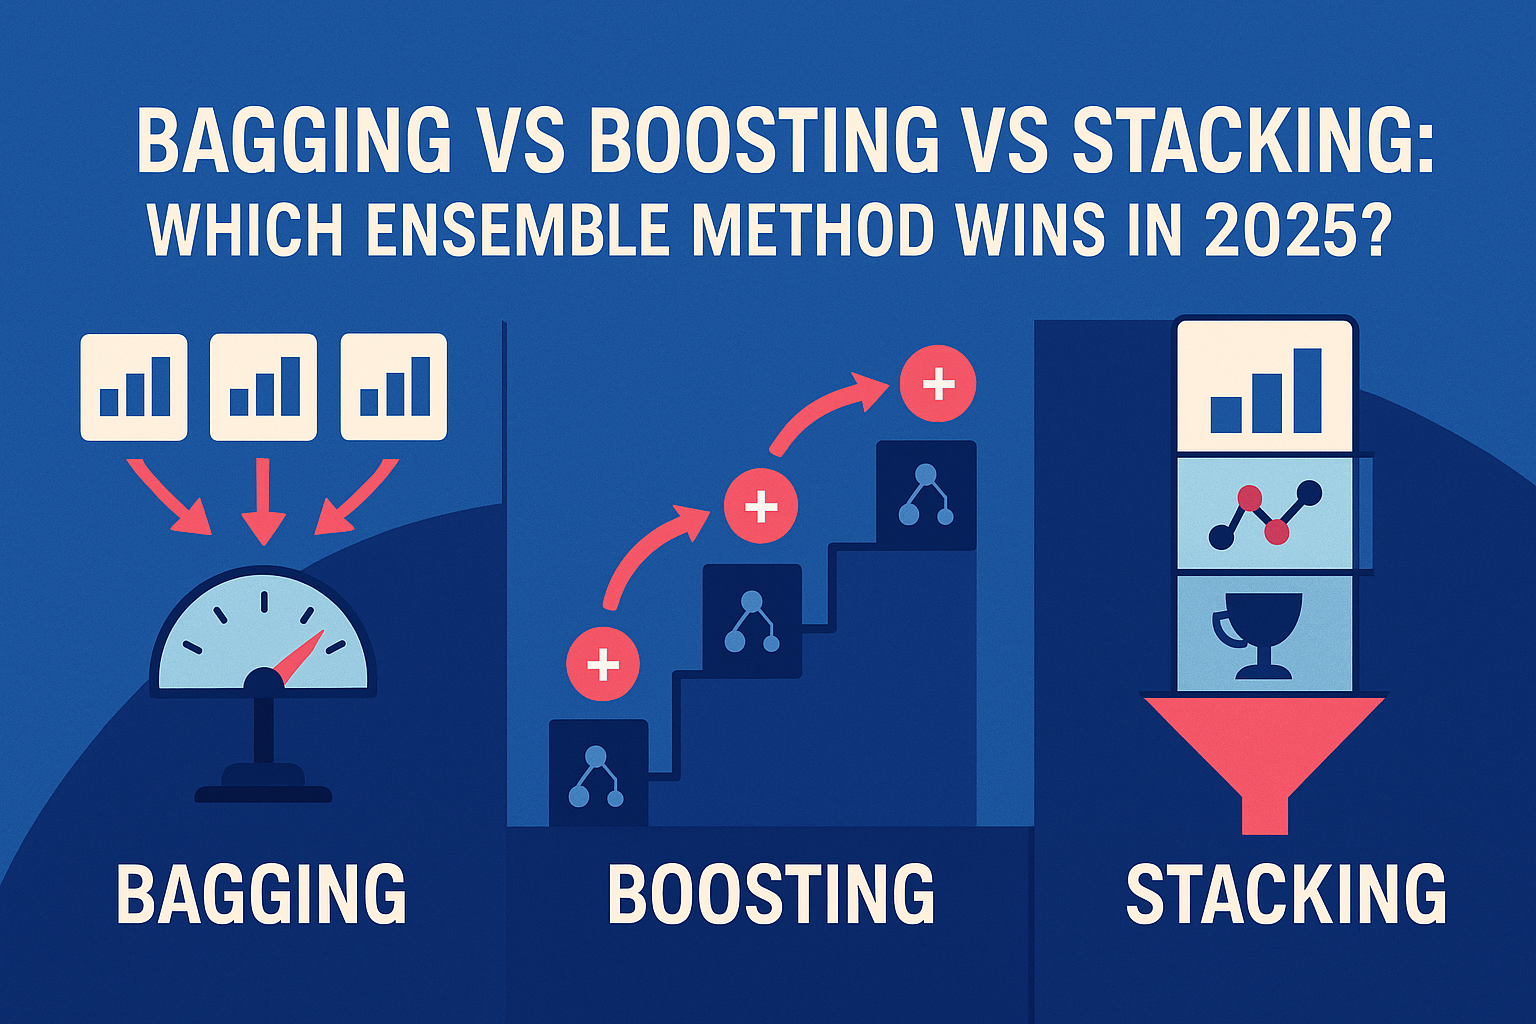
Introduction In machine learning, no single model is perfect.
This article is divided into two parts; they are: • Architecture and Training of BERT • Variations of BERT BERT is an encoder-only model.
Memory is one of the most overlooked parts of agentic system design.
Large language models (LLMs) exhibit outstanding abilities to reason over, summarize, and creatively generate text.
The rise of language models, and more specifically large language models (LLMs), has been of such a magnitude that it has permeated every aspect of modern AI applications — from chatbots and search engines to enterprise automation and coding assistants.
When building machine learning models, most developers focus on model architectures and hyperparameter tuning.
The increasing sophistication of cyber threats calls for a systemic change in the way we defend ourselves against them.