A Gentle Introduction to SHAP for Tree-Based Models
Machine learning models have become increasingly sophisticated, but this complexity often comes at the cost of interpretability.

Machine learning models have become increasingly sophisticated, but this complexity often comes at the cost of interpretability.
Imbalanced datasets, where a majority of the data samples belong to one class and the remaining minority belong to others, are not that rare.
Large language models (LLMs) are widely used in applications like chatbots, customer support, code assistants, and more.
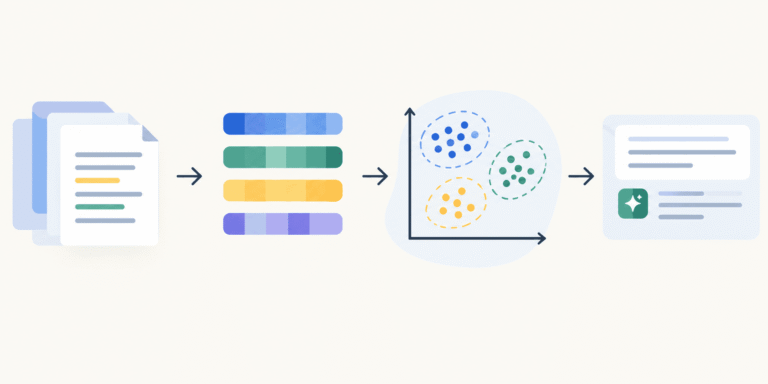
In this article, you will learn how to build a lightweight, end-to-end RAG pipeline using scikit-learn for vector retrieval and open-source models for embeddings and…
In this article, you will learn why a large context window is not the same thing as agent memory, and how techniques like retrieval, compression,…
Quantization is a frequently used strategy applied to production machine learning models, particularly large and complex ones, to make them lightweight by reducing the numerical precision of the model’s parameters (weights) — usually from 32-bit floating-point to lower representations like 8-bit integers.