Navigating Imbalanced Datasets with Pandas and Scikit-learn
Imbalanced datasets, where a majority of the data samples belong to one class and the remaining minority belong to others, are not that rare.

Imbalanced datasets, where a majority of the data samples belong to one class and the remaining minority belong to others, are not that rare.
Before we begin, let’s make sure you’re in the right place.
Matrices are a key concept not only in linear algebra but also with regard to their prominent application and use in machine learning (ML) and data science.
Most AI agent tutorials start with an API.
But cutting your runtime token burn is just the first problem.
This article is divided into four parts; they are: • Preparing Documents • Creating Sentence Pairs from Document • Masking Tokens • Saving the Training Data for Reuse Unlike decoder-only models, BERT’s pretraining is more complex.
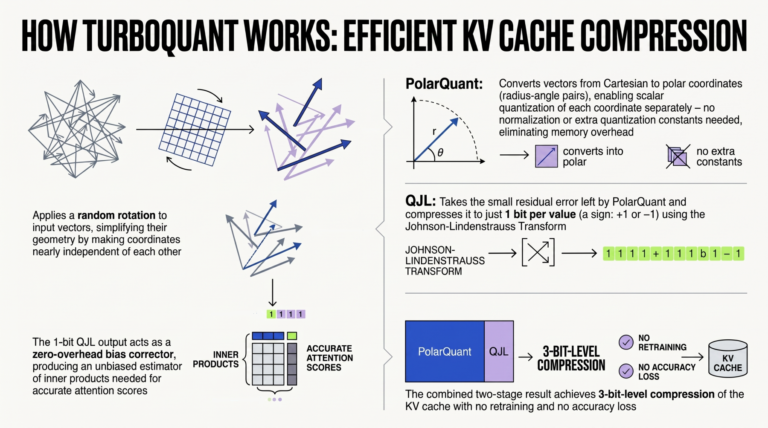
TurboQuant has recently been launched by Google as a novel algorithmic suite and library for applying advanced quantization and compression to large language models (LLMs) and vector search engines — an indispensable element of RAG systems.