6 Lesser-Known Scikit-Learn Features That Will Save You Time
For many people studying data science,

For many people studying data science,
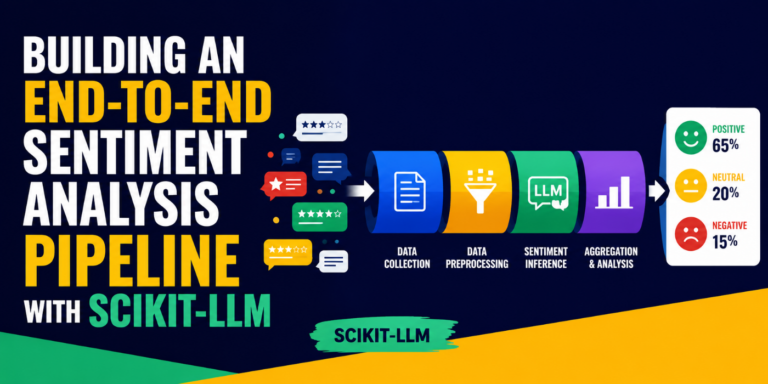
Traditional machine learning pipelines for predictive tasks like text classification usually rely on extracting structured, numerical features from raw text — for instance, TF-IDF frequencies or token embeddings — to feed into classical models such as logistic regression, ensembles, or support vector machines.
Imbalanced datasets, where a majority of the data samples belong to one class and the remaining minority belong to others, are not that rare.
In regression models , failure occurs when the model produces inaccurate predictions — that is, when error metrics like MAE or RMSE are high — or when the model, once deployed, fails to generalize well to new data that differs from the examples it was trained or tested on.
When large language models first came out, most of us were just thinking about what they could do, what problems they could solve, and how far they might go.
Extreme gradient boosting ( XGBoost ) is one of the most prominent machine learning techniques used not only for experimentation and analysis but also in deployed predictive solutions in industry.
Large language models (LLMs) are changing the way we think about AI.