Evaluating Graph-RAG vs. Standard RAG: A Hallucination Benchmark on Fact-Dense Queries
In this article, you will learn how to benchmark a deterministic 3-Tiered Graph-RAG system against a standard vector RAG pipeline on fact-dense queries, and what…

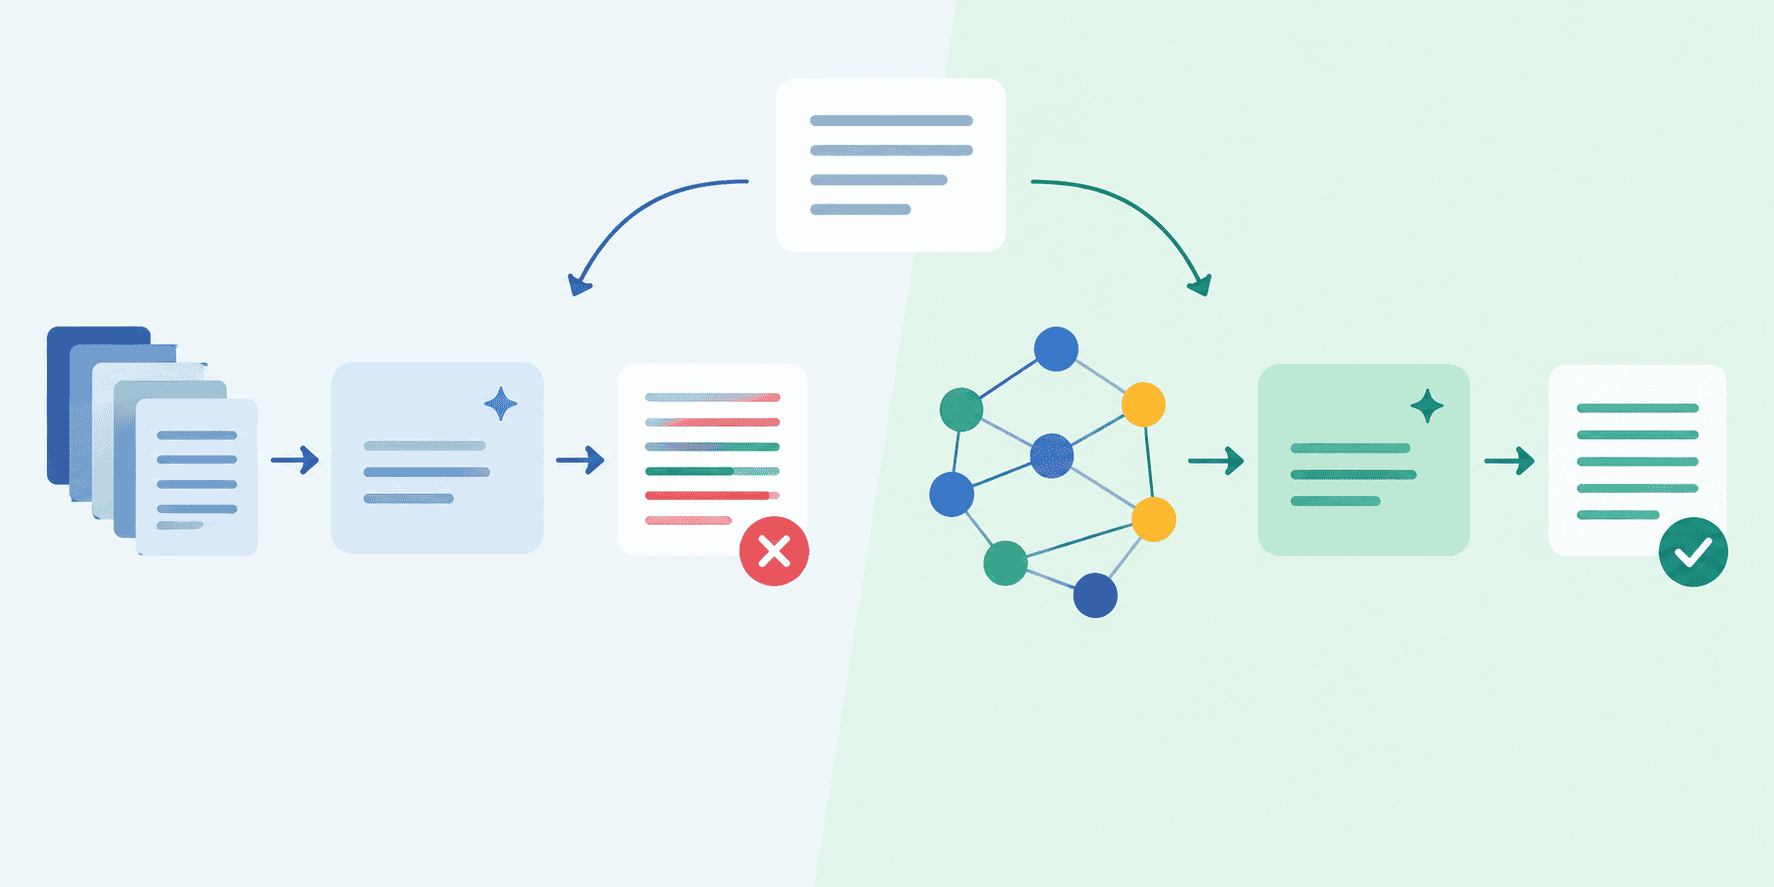
In this article, you will learn how to benchmark a deterministic 3-Tiered Graph-RAG system against a standard vector RAG pipeline on fact-dense queries, and what…
You’ve probably shipped this bug before, where a user types ” affordable laptop ” into your search bar and gets zero results.
Data preparation is a step within the data project lifecycle where we prepare the raw data for subsequent processes, such as data analysis and machine learning modeling.
Building machine learning models in high-stakes contexts like finance, healthcare, and critical infrastructure often demands robustness, explainability, and other domain-specific constraints.
Selecting the right model is one of the most critical decisions in any machine learning project.
But cutting your runtime token burn is just the first problem.
Fine-tuning has become much more accessible in 2024–2025, with parameter-efficient methods letting even 70B+ parameter models run on consumer GPUs.