Context vs. Memory Engineering in Agentic AI Systems
Compression on Arrival Tool outputs should be compressed after a call returns, not after the window fills.

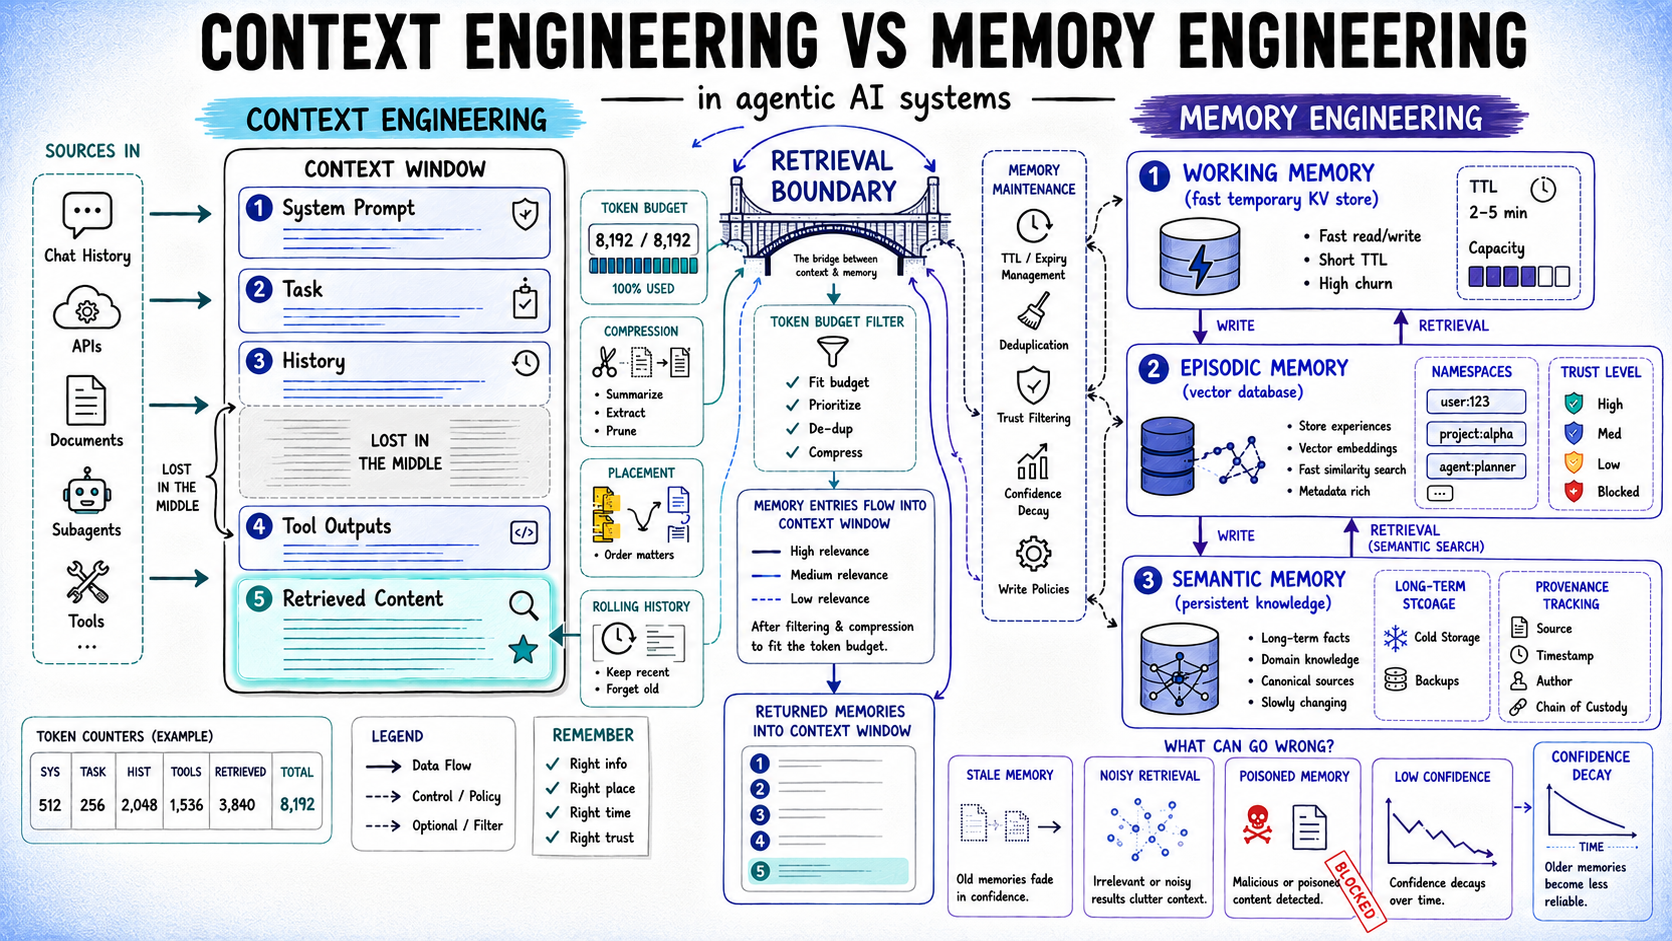
Compression on Arrival Tool outputs should be compressed after a call returns, not after the window fills.
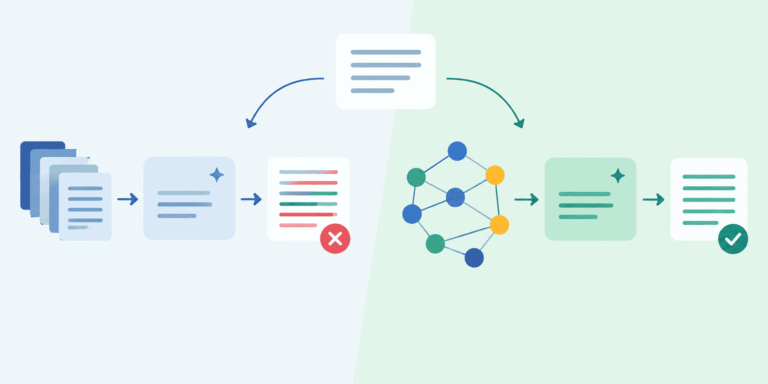
In this article, you will learn how to benchmark a deterministic 3-Tiered Graph-RAG system against a standard vector RAG pipeline on fact-dense queries, and what…
In this article, you’ll learn to: • Turn unstructured, raw image data into structured, informative features.
Large language models (LLMs) are widely used in applications like chatbots, customer support, code assistants, and more.
This article is divided into four parts; they are: • The Problem with Static Batching • Code Example of Static Batching • Continuous Batching: Dynamic Scheduling and Ragged Batching • Full Implementation The simplest way to serve multiple requests together is to use static batching, by grouping them into fixed-size batches and processing each batch…
This post is divided into five parts; they are: • Preparing the Dataset for Training • Implementing the Seq2Seq Model with LSTM • Training the Seq2Seq Model • Using the Seq2Seq Model • Improving the Seq2Seq Model In