Building a RAG Pipeline with llama.cpp in Python
Using llama.

Using llama.
Data merging is the process of combining data from different sources into a unified dataset.
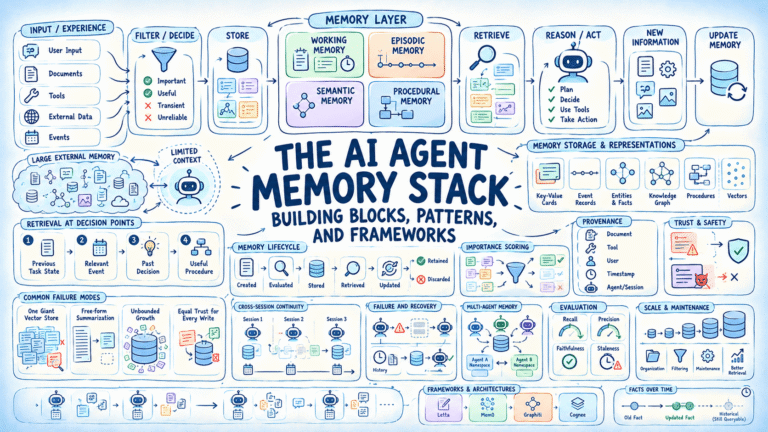
In this article, you will learn how agent memory works, what types of memory exist, and how different frameworks approach storage, retrieval, and memory management…
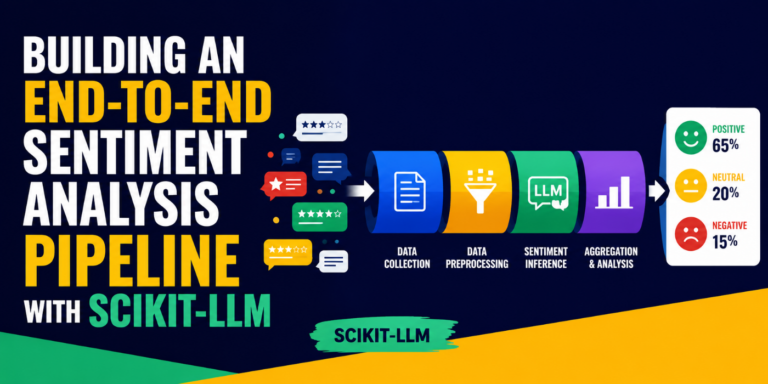
Traditional machine learning pipelines for predictive tasks like text classification usually rely on extracting structured, numerical features from raw text — for instance, TF-IDF frequencies or token embeddings — to feed into classical models such as logistic regression, ensembles, or support vector machines.
Text-based adventure games have a timeless appeal.
Theory is easier to trust once it’s running against a real API, so both examples in this article use the same tool — a get_weather function backed by
In this article, you will learn the key differences between single-agent and multi-agent AI systems, and how to decide which architecture fits your problem. Topics…