Understanding RAG Part VII: Vector Databases & Indexing Strategies
Be sure to check out the previous articles in this series: •

Be sure to check out the previous articles in this series: •
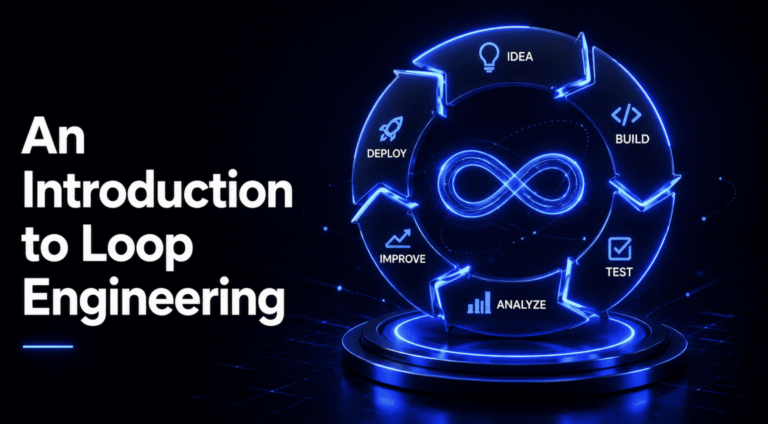
It’s tempting to treat loop engineering as something invented in a single week in June, but the mechanics behind it are closer to five years old, and knowing the lineage is what separates a real understanding of the idea from just repeating the trend piece.
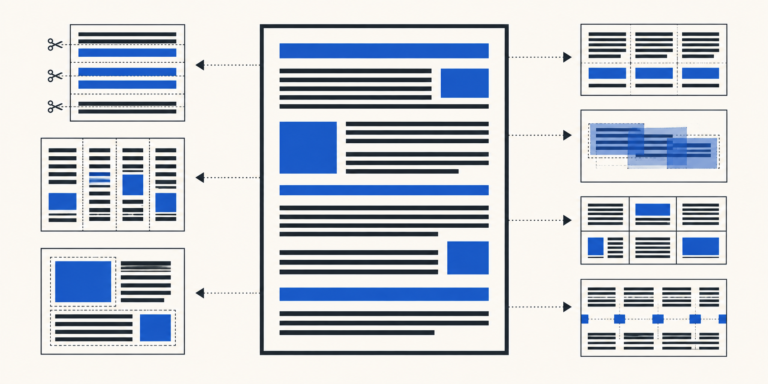
Day 100 in production isn’t really about chunking strategies anymore.
This post covers three main areas: • Why Mixture of Experts is Needed in Transformers • How Mixture of Experts Works • Implementation of MoE in Transformer Models The Mixture of Experts (MoE) concept was first introduced in 1991 by
Kernel methods are a powerful class of machine learning algorithm that allow us to perform complex, non-linear transformations of data without explicitly computing the transformed feature space.
machine learning continues to evolve faster than most can keep up with.
Matrices are a key concept not only in linear algebra but also with regard to their prominent application and use in machine learning (ML) and data science.