7 Regression Tests Every AI Agent Should Pass Before Deploy
In this article, you will learn seven concrete regression tests for catching the orchestration-layer failure modes that matter most before deploying an AI agent to…

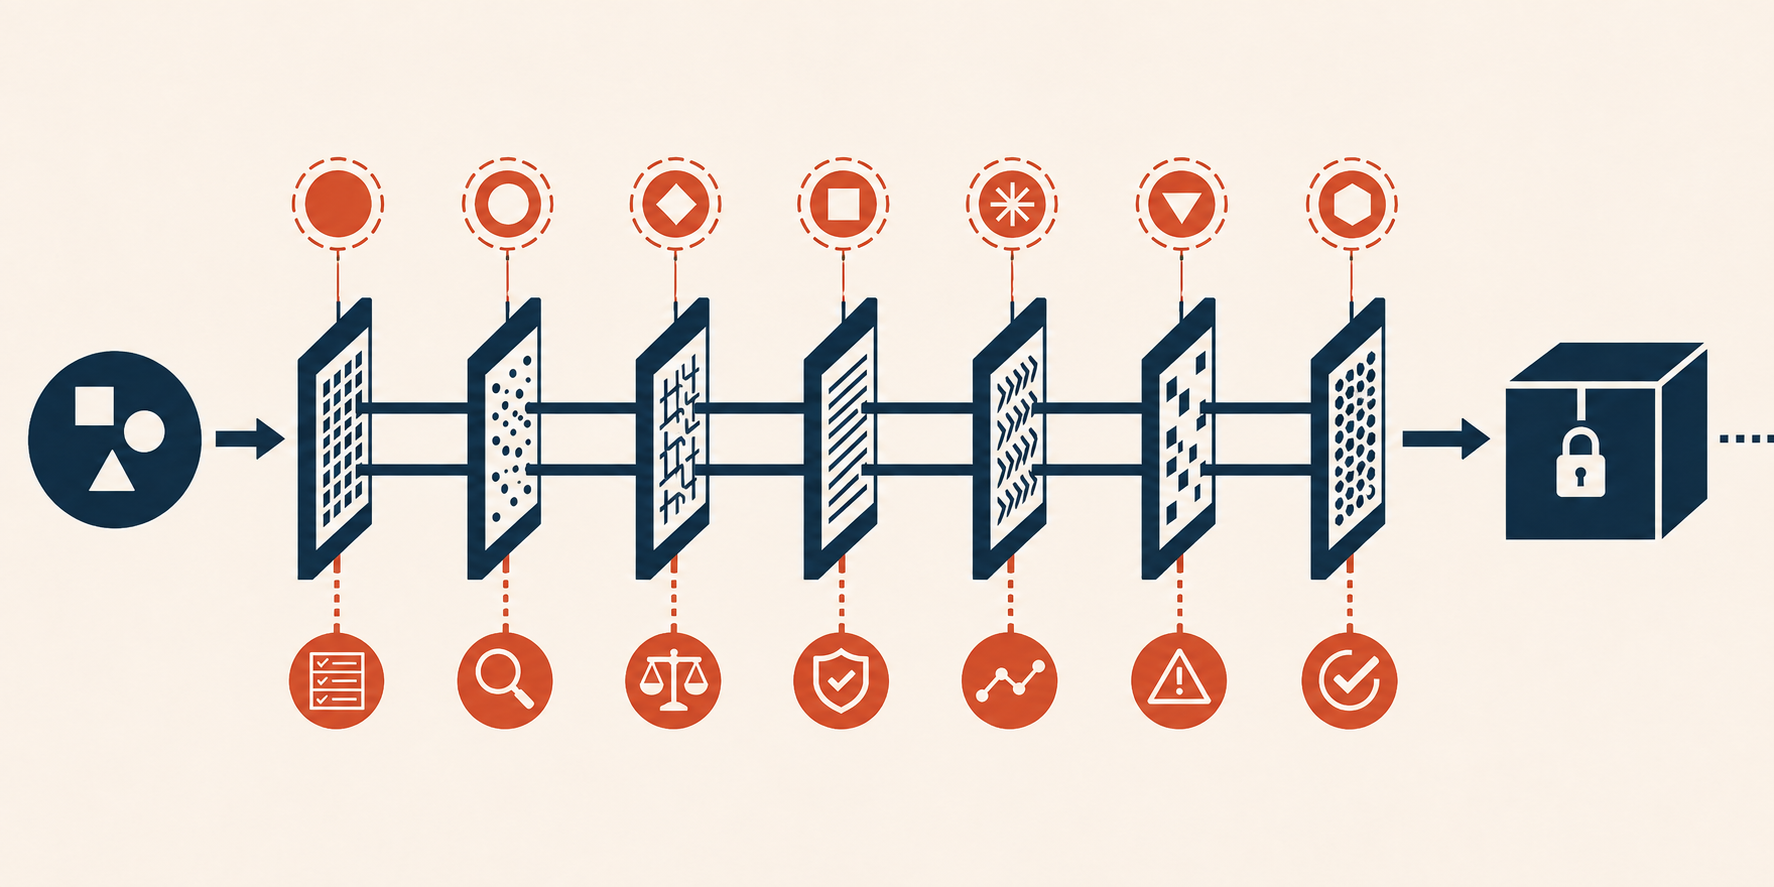
In this article, you will learn seven concrete regression tests for catching the orchestration-layer failure modes that matter most before deploying an AI agent to…
Large language model embeddings, or LLM embeddings, are a powerful approach to capturing semantically rich information in text and utilizing it to leverage other machine learning models — like those trained using Scikit-learn — in tasks that require deep contextual understanding of text, such as intent recognition or sentiment analysis.
Let’s face it: keeping up with new research, tools, and industry shifts in machine learning can be down-right overwhelming.
Text classification typically boils down to scenarios where a product review is “positive” or “negative”, or a customer inquiry belongs to one category or another.
When working with machine learning on structured data, two algorithms often rise to the top of the shortlist: random forests and gradient boosting .
You’ve probably shipped this bug before, where a user types ” affordable laptop ” into your search bar and gets zero results.